Process Unstructured Content using AWS ML Services.
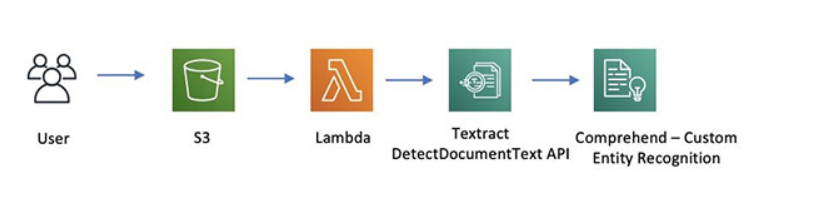
In this project, We develop a robust model for processing unstructured content, extract valuable insights from the data, and enable automation and data-driven decision-making, thereby enhancing operational efficiency and facilitating informed decision-making within organizations.
AWS Services:
Amazon S3
Amazon Lambda
Amazon Textract
Amazon Comprehend
Practical Implementation
We process resume documents from the Resume Entities for NER dataset to get insights such as candidates' skills by automating this workflow, we use Amazon Textract to extract text from these resumes and Amazon Comprehend custom entity recognition to detect skills such as AWS, C, and C++ as custom entities.
Launching CloudFormation Stack
Step 1: Log in to AWS Console
Step 2: Cloudformation template download this template in your local machine
Step 3: Go to CloudFormation--> Create Stack
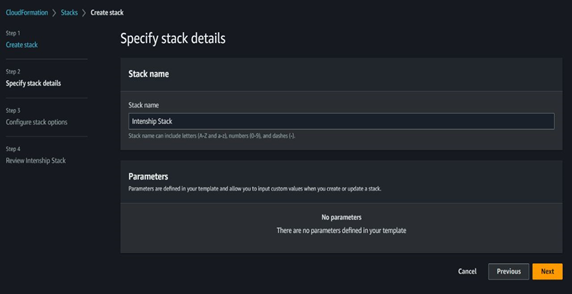
Step 4: Fill The details
Leave other things as it is.
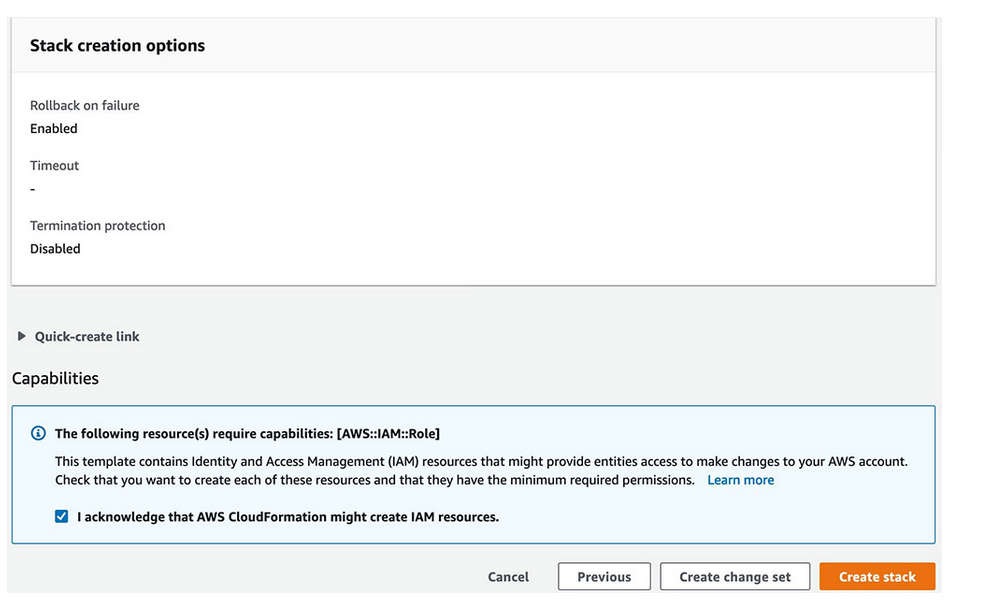
Wait for the stack to finish running.
Step 5: On the Output tab of the Cloudformation stack, record the sagemaker URL.
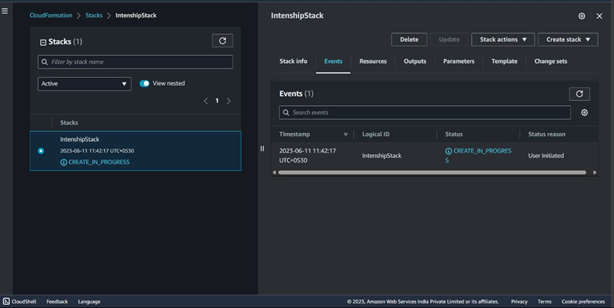
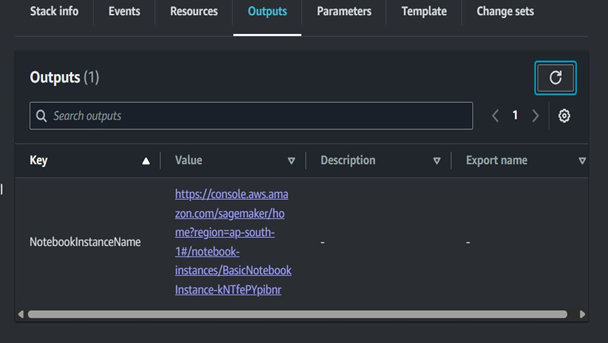
Running Workflow on Jupyter Notebook
Step 1: Open Sagemaker URL.
Step 2: Under the New drop-down menu Choose Terminal
Step 3: On the Terminal
cd sagemaker;clonehttps://github.com/aws-samples/amazon-custom-entity-recognition-textract-comprehend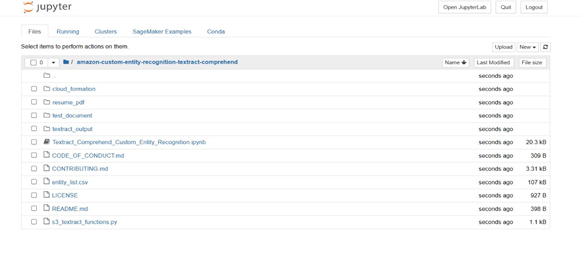
Step 4: Open
Textract_Comprehend_Custom_Entity_Recognition.ipynbStep 5: Run the Cells.
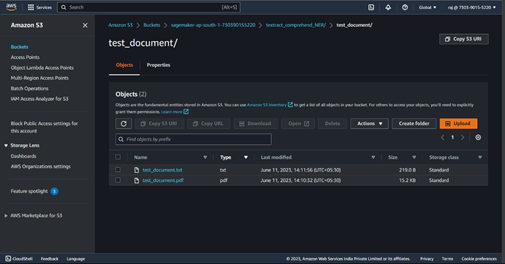
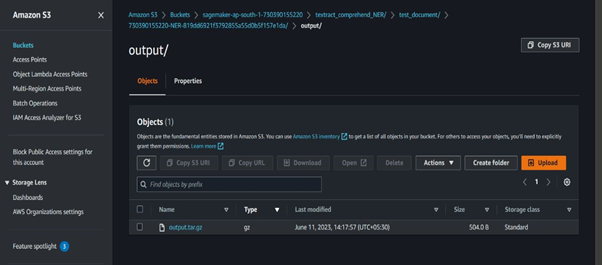
After Running the cells. we have to check that Bucket is created or not
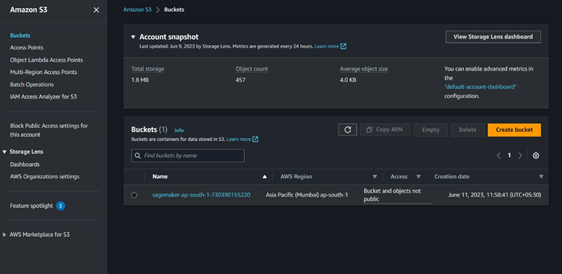
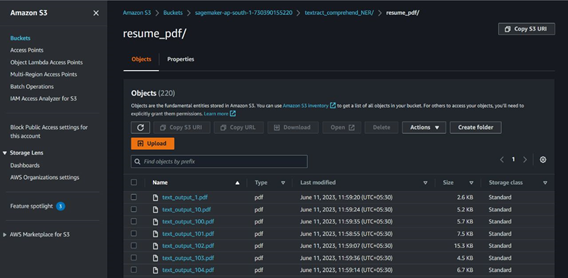
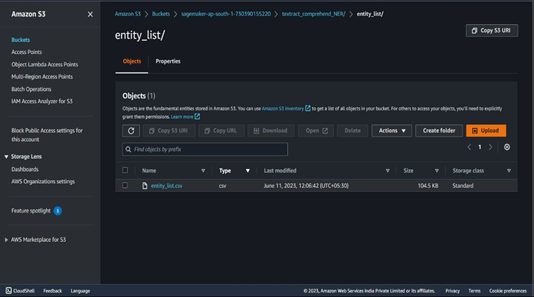
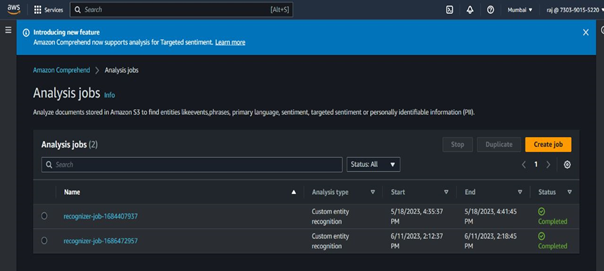
Go to Comprehend
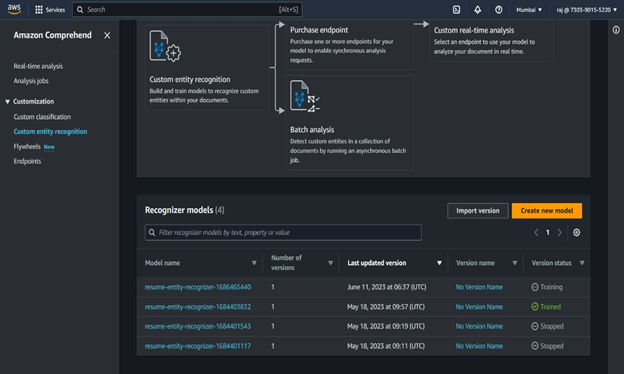

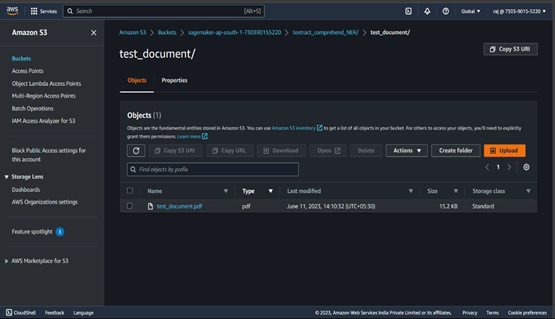
Conclusion:
The integration of Amazon Textract and Amazon Comprehend provides a powerful solution for extracting custom entities from documents. By leveraging Textract's document processing capabilities and Comprehend's entity recognition capabilities, businesses can automate the extraction of specific information that is relevant to their domain. This enables streamlined workflows, improved efficiency, and valuable insights from text-based documents.
